HOW TO MEASURE AGENTIC REVENUE ENABLEMENT
SEP 30, 2026






Agentic revenue enablement is the use of autonomous AI agents, not just AI-assisted features, to complete enablement work on their own. An agent that flags a stalled deal, drafts the follow-up, and answers a rep's question inside a live deal room without anyone asking it to is doing agentic work. So is an agent that notices a rep is under-prepared for a vertical they've never sold into and assigns a practice run before the call, not after the deal is already lost. Measuring it means tracking six things at once:
Agent adoption and trust
Action-to-outcome conversion
Content and answer intelligence accuracy
Deal and revenue attribution
Rep readiness and skill coverage
Time saved per rep
A rep on your team gets a notification at 6am. A deal that's been quiet for eight days just got flagged, and by the time she's at her desk with coffee, a follow-up email is already drafted and waiting for her signoff. Down the hall, a rep who's never worked a healthcare account gets assigned a roleplay simulation before his first call with one, because the agent noticed the gap before his manager did. Nobody asked the system to do either of those things. It just did.
That's agentic revenue enablement, and if your team has adopted any part of it (or is about to), you've probably run into the same wall everyone else has: you can tell the agent is doing things. You just can't tell if any of it is working. Asset views, login counts, and completed-course checkmarks, the metrics enablement and readiness teams have leaned on for a decade, don't have anything to say about an AI agent that acts on its own. This piece is a practical measurement framework for agentic revenue enablement: six pillars spanning both content and coaching, a step-by-step way to build a scorecard around them, and what to actually look at once you have one.
What Makes "Agentic" Different From Regular Revenue Enablement Tools
Most of what got called "AI" in revenue enablement over the last few years was really just AI-assisted: a tool suggests something, a human decides whether to act on it. Agentic is a different animal. The agent doesn't wait to be asked. It notices a deal has gone cold, drafts the email, surfaces the risk to a manager, and only then does a human step in (usually just to approve, not to originate).
That distinction matters more than it sounds like it should, because it changes what you're actually measuring. With AI-assisted tools, you're measuring whether people use a feature. With agentic tools, you're measuring whether an autonomous decision led somewhere good, which is a completely different kind of question (and one most enablement dashboards were never built to answer).
Revenue enablement can mean a lot of things depending on who you ask, but the agentic layer specifically is about handing the agent enough context, deal history, content library, buyer signals, that it can act without a human filling in the gaps first.
None of this means the human disappears from the loop, whatever the more breathless AI headlines might suggest. It means the human's job moves from "originate the action" to "review the action," which is a smaller job, but not a zero job. Guardrails still matter (an agent that can draft a follow-up shouldn't necessarily be allowed to send it unsupervised on a six-figure deal), and where you draw that line changes what "adoption" even means for your team. That's worth deciding before you start measuring anything, not after.
Why Traditional Enablement Metrics Don't Capture Agentic Impact
Here's the uncomfortable part: sales reps already spend 60% of their time on work that isn't selling, according to Salesforce's 2026 State of Sales research, chasing decks, updating CRM fields, waiting on approvals. That's exactly the kind of work agentic AI is supposed to claw back. But if you're still measuring success with the same asset-view and login metrics you used for your content library, you'll never know whether the agent actually clawed any of it back or just added another dashboard nobody checks.
There's a second failure mode that's sneakier: false adoption. An agent can rack up impressive usage numbers (queries answered, nudges sent, summaries generated) while reps quietly ignore half of what it produces. Usage without follow-through isn't adoption. It's noise with a good uptime record.
Your business probably already tracks KPIs for its human-run enablement programs, and that instinct is right. It just needs a second, parallel set of metrics built specifically for what an autonomous agent does differently than a human coach or a content library ever could.
The 6-Pillar Measurement Framework
Measuring agentic revenue enablement comes down to six categories: how often reps actually use and trust the agent, how many of its suggestions turn into completed actions, how accurate its answers and content picks are, how those actions trace back to real deal and revenue outcomes, whether reps are actually ready for the deals in front of them, and how much time it's actually saving per rep. Track fewer than that and you'll miss where the agent is quietly failing. Track more and you'll drown your team in dashboards nobody opens.
Pillar 1: Agent Adoption & Trust
Adoption here isn't "did someone open the tool." It's query volume relative to team size, repeat usage over weeks (not just a first-week novelty spike), and the override or dismissal rate, meaning how often reps see a suggestion and ignore it. A high dismissal rate is a trust problem, not a UI problem, and it's worth treating it that way.
A manager asking the AI agent a pipeline question directly, in plain language, instead of building a report.
Salesforce found that 94% of sales leaders who've adopted agents call them essential for meeting business demands. That's a strong signal of leadership trust. Whether the reps actually doing the selling feel the same way is the number you need to track yourself, because it won't show up in anyone else's survey.
Pillar 2: Action-to-Outcome Conversion
This is the number that actually answers "is this worth it": of everything the agent recommended or flagged this month, what percentage turned into a completed rep action within a reasonable window? An agent that generates 500 nudges a week and gets 40 of them acted on is not a productivity win, whatever its usage chart looks like.
The queue of agent-recommended actions a rep sees each morning, the raw feed this metric is built from.
The same conversion metric rolled up across a manager's whole team.
Reps who work alongside AI tools report hitting their targets more often (88%, per Salesforce), and that's the outcome you're chasing here. Action-to-outcome conversion is the metric that tells you whether your specific setup is actually producing that result or just generating activity.
Pillar 3: Content & Answer Intelligence Accuracy
When a rep asks the agent a question mid-deal, does it answer correctly without escalating to a human? Track deflection rate (questions resolved without a person stepping in) alongside a periodic accuracy spot-check, because a high deflection rate on wrong answers is worse than no deflection at all.
An AI-generated answer surfaced directly inside the content search experience, the exact moment this metric is measuring.
Pillar 4: Deal & Revenue Attribution
This is the pillar that gets you a seat at the revenue conversation, not just the enablement one. Compare cycle time and win rate on deals where the agent flagged risk or recommended an action against deals where it stayed quiet. If there's no meaningful gap, something in Pillars 1 through 3 needs fixing before this one will move.
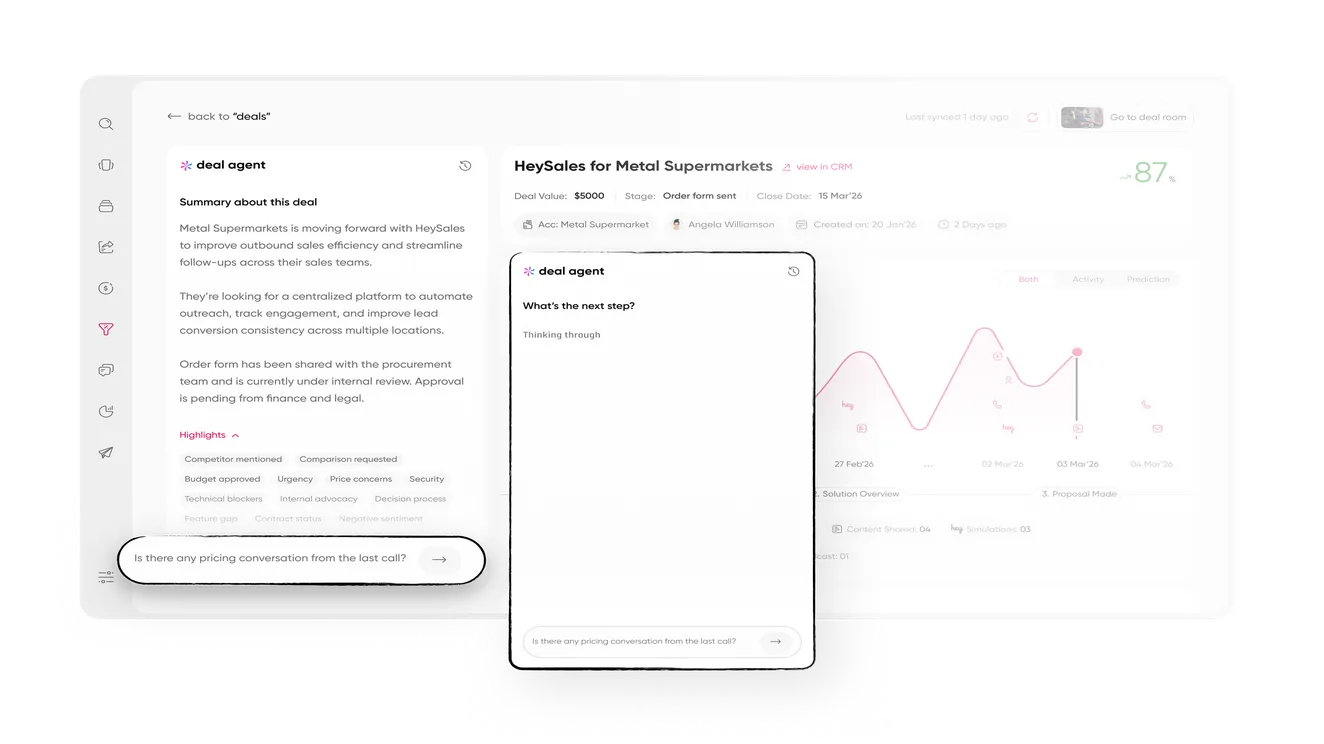
The agent operating at the individual deal level, where attribution actually gets traced back to a specific outcome.
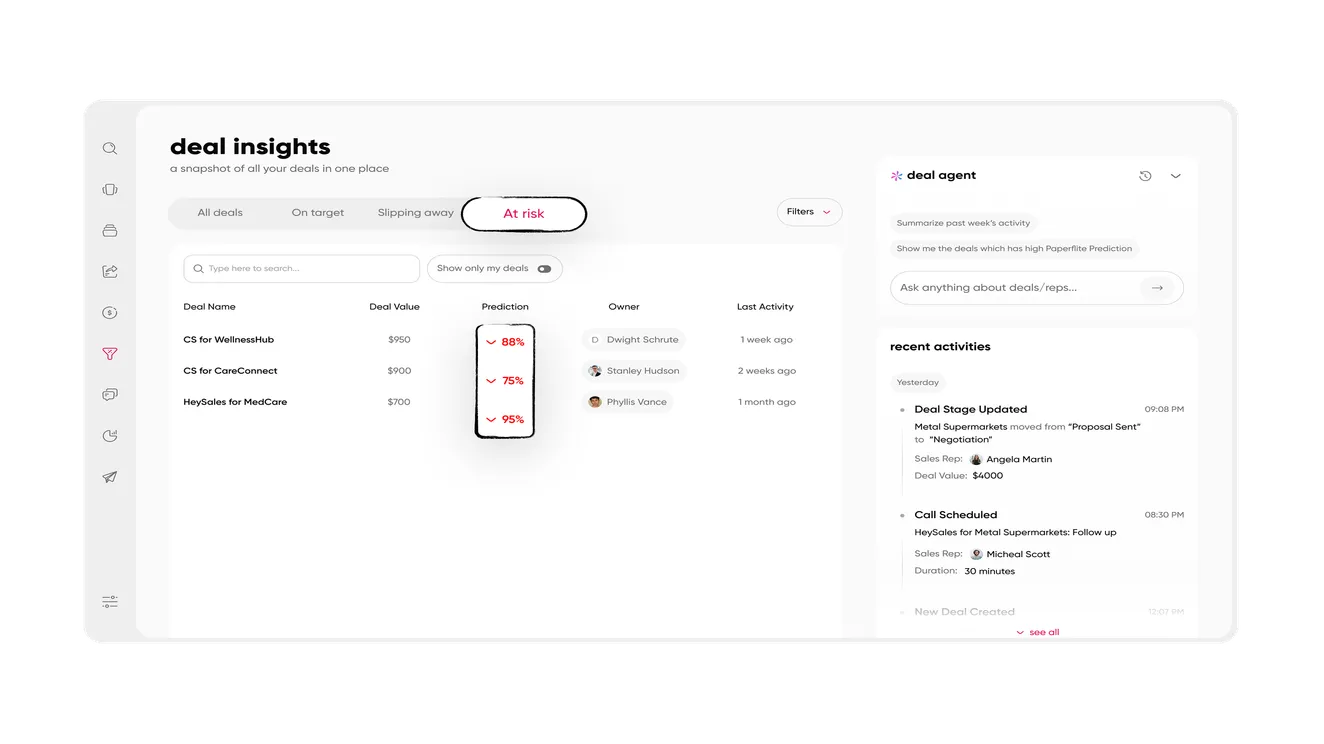
The at-risk flagging view that feeds directly into the attribution comparison above.
Sellers using AI tools are 3.7 times more likely to hit quota, according to the same Salesforce research. That's the kind of number this pillar is built to validate (or challenge) against your own pipeline, not just take on faith from someone else's report.
Pillar 5: Rep Readiness & Skill Coverage
This is the pillar most agentic revenue enablement frameworks skip, and it's the one that determines whether the other four even matter. An agent can flag every stalled deal and draft every follow-up perfectly, but if the rep on that deal doesn't have the vertical knowledge or objection-handling skill to close it, the deal still stalls. Sales readiness has always been a coaching problem. The agentic version is a manager not having to notice the gap first.
The agent flagging an at-risk rep the same way Pillar 4 flags an at-risk deal, before a manager has to go looking for it.
A readiness score broken down by skill area, the actual number this pillar is built to track over time.
Track readiness score trend by rep and by team, skill-gap closure rate after a flagged simulation or coaching nudge, and how a rep's readiness compares against your own high performers, not an industry benchmark that doesn't know your product or your buyers.
Pillar 6: Time Saved Per Rep
Hours reclaimed from manual follow-ups, pipeline summaries, and digging through the content library for the right asset. This one's blunt on purpose: if reps can't point to time they got back, the rest of the framework is measuring activity that isn't actually helping anyone.
An AI-generated weekly summary standing in for what used to be a manual reporting task.
Building Your Scorecard, Step by Step
You don't need all six pillars fully instrumented on day one (nobody does). Here's the order that actually works.
Baseline for 30 days before you touch anything. Capture your current numbers, deal cycle time, win rate, hours spent on manual follow-up, before the agent is doing much of anything. Without this, every later number is a guess dressed up as an insight.
Pick two or three metrics per pillar, not all eighteen. A scorecard nobody can explain in one sentence is a scorecard nobody checks.
Put RevOps in the review, not just enablement. Attribution and revenue metrics need someone who already owns the pipeline data, or you'll spend more time arguing about whose number is right than acting on it. Enablement and sales management can own Pillars 1, 2, 3, and 5 on their own. Pillar 4 needs a joint owner with RevOps, and Pillar 6 is worth reviewing jointly too, since "time saved" means something different to a rep than it does to finance.
Recalibrate every quarter. Rep trust in the agent shifts as it gets better (or as reps find its blind spots), and a scorecard built for month one won't fit month six.
The Scorecard at a Glance
Agent Adoption & Trust: query volume per rep and dismissal rate, reviewed weekly.
Action-to-Outcome Conversion: percentage of nudges completed, reviewed weekly.
Content & Answer Accuracy: deflection rate and spot-check accuracy, reviewed monthly.
Deal & Revenue Attribution: win rate delta and cycle time delta, reviewed monthly.
Rep Readiness & Skill Coverage: readiness score trend and skill-gap closure rate, reviewed monthly.
Time Saved Per Rep: hours reclaimed per week, reviewed quarterly.
How Paperflite and HeySales Make This Measurable
Most of the framework above is hard to instrument because the underlying agent doesn't expose the data cleanly, if you can't see the query, you can't measure the trust. Paperflite and HeySales are built around the deals, content, and coaching your team already lives in, which means the data for this scorecard already exists where you'd look for it, split across the two sides of the same problem: content and deal intelligence on one side, rep readiness on the other.
On the content and deal side, Deal Agent answers pipeline questions and in-deal queries in plain language, which is exactly the raw material Pillar 1 needs. Nudges surface prioritized actions for reps and track whether they're completed, so Pillar 2 isn't something you have to reconstruct after the fact. Seek AI Search answers content questions inside the content hub and logs whether a rep needed to escalate, feeding Pillar 3 directly.
An AI-generated deal room summary, agentic summarization operating inside a live, active deal.
On the readiness side, this is where HeySales does the work Pillar 5 depends on. Its AI Coaching diagnoses a rep's skill gaps on its own, the same agentic pattern as Deal Agent flagging a stalled deal, just pointed at a person instead of a pipeline. From there it can assign an AI Persona Roleplay simulation before the gap turns into a lost deal, and roll individual readiness scores up against your own high performers rather than a generic industry curve.
HeySales diagnosing a coaching need on its own, before a manager has flagged anything.
None of this replaces the framework, on either the Paperflite or the HeySales side. It just means you're not building the instrumentation from scratch before you can use it.
If you'd rather see Deal Agent, Nudges, and HeySales' AI Coaching catch these gaps in your own pipeline than take this framework on faith, book a demo and we'll run it against your actual deal data.
Adoption alone was never the win condition, even back when "AI" in revenue enablement just meant a chatbot bolted onto a content library. It matters even less now that the agent is acting on its own, whether it's flagging a deal or a rep's skill gap. What matters is whether those actions convert, whether the content it surfaces is right, whether reps were actually ready for the deals they were in, and whether any of it shows up in a deal that actually closed faster or bigger than it would have otherwise. Build the measurement framework for agentic revenue enablement before you scale the agent, not after, and you'll spend a lot less time arguing about whether it's working and a lot more time making it better.
For the tools, tactics, and reasoning that go beyond agentic AI specifically, this framework sits inside the broader set of revenue enablement practices most RevOps teams are already building toward, including the best practices that apply whether or not an agent is involved.
What is agentic revenue enablement?
Agentic revenue enablement is when AI agents complete enablement work on their own instead of just suggesting it to a human first. That includes flagging at-risk deals, drafting follow-ups, answering rep questions inside a deal, and summarizing pipeline activity, all without someone explicitly asking for it each time.
How is agentic revenue enablement different from AI-assisted enablement?
AI-assisted tools suggest something and wait for a human to act. Agentic tools act first and loop a human in mainly to approve or override. That shifts what you measure, from "did someone use this feature" to "did this autonomous action lead somewhere good."
What metrics matter most for measuring AI agents in revenue enablement?
Six categories cover it: agent adoption and trust, action-to-outcome conversion, content and answer accuracy, deal and revenue attribution, rep readiness and skill coverage, and time saved per rep. Most teams already track something like the first one and completely miss the other five.
Where does sales readiness fit into agentic revenue enablement?
Readiness is the pillar that decides whether the other five actually pay off. An agent can flag every stalled deal correctly, but if the rep on it isn't prepared for that buyer or vertical, the deal stalls anyway. Agentic readiness tools diagnose a rep's skill gaps and assign practice on their own, the same pattern as an agent flagging a deal, just aimed at a person instead of a pipeline.
How do you calculate ROI on revenue enablement AI agents?
Compare win rate and deal cycle time on deals where the agent flagged risk or recommended an action against deals where it didn't. The gap between those two groups, not the agent's usage stats, is the closest thing you'll get to a real ROI number.
How long before agentic revenue enablement metrics are reliable?
Baseline your current numbers for 30 days before the agent has much influence, then give it another 60 to 90 days of activity before drawing conclusions from the attribution pillar specifically. Adoption and action metrics turn useful much sooner, usually within a few weeks.
Is agentic AI actually worth it for revenue enablement teams?
The teams seeing results treat it as a measurement problem first and a technology problem second. Salesforce's research found sellers using AI tools are 3.7 times more likely to hit quota, but that number only holds if someone's actually tracking whether the agent's specific recommendations are landing, not just whether it's turned on.
How do I get started measuring this with Paperflite and HeySales?
Start with a 30-day baseline of your current pipeline and readiness metrics, then turn on Paperflite's agentic features (Deal Agent, Nudges, and Seek AI Search) alongside HeySales' AI Coaching and roleplay simulations, and layer the six-pillar scorecard on top.
Frequently Asked Questions
PAPERFLITE'S CONTENT TECHNOLOGY IN ACTION
IT'S EASIER THAN FALLING OFF A LOG
(DON'T ASK US HOW WE KNOW THAT)